THE PRAGMATIC MESH SERIES | PART 8
Previously: Parts 1 to 5 argued that data initiatives fail for organizational reasons, and made the case for small, business-owned domain teams, a platform that keeps them small, open standards and lean governance rituals. Part 6 (Who Is in Charge of Your Lakehouse?) argued that every important data product needs one named owner who can decide. Part 7 (The Semantic Layer You Already Have) argued that your domain-owned apps already are a semantic layer, and that AI only needs a thin map, skills.md, that routes each business concept to the app that owns it. Part 7 also drew a line: an agent may calculate what the map does not cover, as long as the answer is flagged as an unofficial calculation. This part is about that line.
A note on perspective: as in Parts 3 to 7, I work mostly with Qlik and the examples use it. The argument holds on any platform.
A Confident Number for a Metric Nobody Owns
Picture a Thursday afternoon. The board deck is due on Monday, and someone in the CFO’s office asks the company’s AI assistant: “What was our net revenue retention last year?”
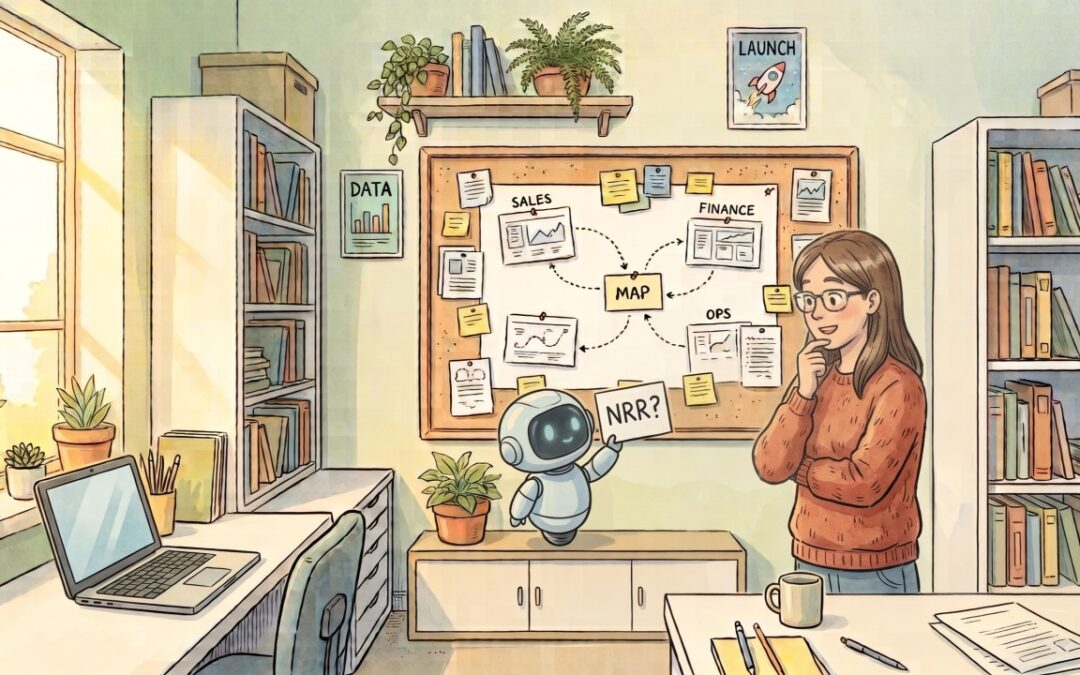
Nobody has defined net revenue retention in any app. It is a textbook SaaS metric, so some users still assume it has been already been implemented. Finance has an ARR app with recurring revenue per customer. Ops owns churn. The thin map acting as semantic layer described in part 7 has entries for the aforementioned but none for NRR. The agent doesn’t stop. It takes total ARR at the end of both years, divides one by the other and returns 118%, in a clean chart. The number goes into the deck.
Here is the problem. Net revenue retention measures how much the customers you already had at the start of the year pay you at the end of it: their expansion, minus their downgrades and churn. New customers should be excluded, to avoid all new deals as retention.
Run the numbers. ARR grew from 10 million to 11.8 million, and 2.2 million of the 11.8 comes from customers who signed during the year. So the customers you started the year with now pay you 9.6 million compared with previous year’s 10: a net revenue retention of 96%. The board sees 118%, a story of happy customers buying more, when the real story is that existing customers are shrinking and new sales are hiding it. The opposite conclusion, delivered with total confidence.
Nothing failed technically. Every number the agent used was correct. What went wrong was the meaning: the agent walked off the edge of the map and kept going, and nothing in its answer said so.
The Agent did its own calculation. That is often valuable, as long as it is properly flagged for validation.
Refuse, Bluff or Label?
The business changes every week, and some new questions will always be about things nobody owns yet. A map has edges too, because it only routes to definitions that already exist. This is often called the semantic gap.
The critical question is what the agent does when it reaches the gap. It has three options:
- It refuses. One semantic-layer vendor puts the case for loud failure well: “With text-to-SQL, failure looks like a plausible but incorrect answer. With the Semantic Layer, failure looks like an error message.” An error message is honest. But a user with a deadline doesn’t give up. They export the data and paste it into a chatbot, and the same improvised number exists anyway, invisible to everyone, with even less traceability.
- It bluffs. It improvises silently. That is the board deck above.
- It labels. It improvises, and says so. This is often the best option and here is how to make it work.
Improvise, But Say So
When the agent reaches a concept with no route, it should do four things:
1. It labels the answer as an unofficial calculation. The answer arrives marked, with the formula it used, the sources it read and the closest governed measures it found. The label is built into the output itself: the chart title, the table header, the file name.
Had the agent shown its first attempt this way, with “How: total ARR 2025 divided by total ARR 2024”, the CFO’s analyst would have caught the mistake in ten seconds. The label does not make a number right. It makes it checkable. A bare number copied into a slide can still lose its label, which is one reason step 3 records who received it, in addition to writing it as a comment on the slide.
The card gets the math right, and it is still unofficial, because even a correct formula rests on decisions that belong to Finance and have not been made yet. Does a customer who moves to a free plan count as churned? Are currency effects removed? What happens when two customers merge? Until Finance answers, the honest label is “unofficial”.
Labeling as such is not new: some BI assistants already mark an answer as verified when it comes from a query an expert prepared in advance. What the mesh adds is where an unofficial answer leads: to the domain owner who can make it official.
2. It never writes the improvised formula back. Not into the map, not “just for next time”. The map holds routes to definitions someone owns, and nothing else. The moment an agent stores its own formula as a definition, the map has started computing meaning instead of routing to it, and the line is crossed from the inside. The agent may draft a proposal; a person decides. Self-improving, never self-modifying.
This will be tempting to relax, because the agent’s proposals will often be right and approving them will start to feel like a formality. That is how meaning drifts back to the center instead of being owned by business, one sensible shortcut at a time.
3. It logs the gap. What was asked, which formula it used, which sources it read and who received the answer. A shared list the agent appends to through a connector is enough. Give the log the same access rules as the data it describes, because a question about next quarter’s board numbers is confidential in itself.
4. It tells the likely owner, in a digest, not a ping. A single question is just logged. A question that keeps coming back, say five times from three different people, goes to the owner of the nearest domain in a weekly digest: “Net revenue retention was requested eight times this month, twice for a board deck. Nobody owns it. Is it yours?”
The default is a choice, not a law. For regulated or external reporting, set the agent to refuse and hand the question to the owner instead. Improvising suits Thursday afternoon’s draft, not the annual report.
The same steps handle ambiguity. When “revenue” could mean Finance’s recognized revenue or Sales’ closed-won bookings, both governed, the agent doesn’t quietly pick one. It shows both, with their owners, asks which was meant and logs it. Part 7’s rule that “a contested concept is surfaced, not merged” stops being an intention and happens, with a record.
A number in a board deck either comes from a governed definition or carries the unofficial flag that requires proper validation before presenting.
Count the Questions, Don’t Predict Them
A gap log turns the usual approach around. You don’t predict the questions the business will ask; you count the ones it does ask. Counting itself is not new: any central layer can mine its query logs, and some BI tools now show their admins which questions their AI assistant could not answer. The difference is who acts on the count: the admins and the data team, or the domain that owns the meaning.
Landscape architects know the pattern. People don’t always walk where the planners put the pavement; they wear their own paths into the grass. These are called desire paths, and the sensible response is not a fence. It is to pave them. The gap log is that trail in the grass: what the business needs that nobody has defined yet.
When a question keeps coming back, it graduates:
- The owner decides. The nearest domain owner, here Finance, decides whether net revenue retention is theirs, and makes the calls only they can make: free plans, currency, mergers.
- The definition goes where definitions belong. It becomes a master measure in the Finance ARR app, next to the data it is computed from. AI can help draft it, since Qlik’s MCP server already lets assistants use and extend an app’s semantics, but the owner signs it.
- Only then does the map get a route. The new entry points to the new measure, and the Release Notes Channel from Part 5 announces it. Because the log recorded who received the improvised figure, “please replace any earlier figures” reaches the people who actually have one.
Meaning is made in the domain, by a person, and the map learns about it afterwards. Never the reverse.
Quarterly Swamp Draining gets a second agenda item: the most-asked questions with no route nor owner. Because the nearest owner said no but the question keeps repeating, it is escalated to the quarterly review instead of being buried in logs forever. A metric asked for forty times that nobody will own is a finding in itself.
Don’t try to predict every question. Count the ones people actually ask.
The Hard Part: Knowing You Have Left the Map
All of this assumes the agent can tell “no governed definition exists” from “a governed definition exists and I didn’t find the route”. That is the hardest unsolved problem in this design. Get it wrong one way, and the agent improvises over a perfectly good governed measure. Get it wrong the other way, and it flags things it could have answered properly.
The safe default is simple: when unsure, treat it as a gap. Calculate, flag the answer as unofficial and show the closest governed measures, so the person can switch to an official one if it fits. A clear “I couldn’t find an official definition, so this is my own calculation” beats a quiet wrong number.
Two habits make the boundary clearer. Write the near-misses down: a “Not this” line in a map entry tells the agent which similar-looking measure is not the one being asked for. And let each domain declare its known gaps in its own file: “Net revenue retention: not defined yet, ask Finance.” A map that knows where it ends is worth more than one that looks complete.
Someone has to read the log. That is the standing job of a steward of the map’s health: a person accountable for the map as a routing system. The steward reads the log, brings real gaps to the owners and sends missed routes back to their domains. A missed route usually means a description was written badly, and the log now shows which sentence to fix. The steward doesn’t decide the exact definition of net revenue retention, only makes sure the right owner hears that someone needs it.
Signed or Flagged
Every answer an agent gives should fall into one of two kinds:
- Routed and signed: the map points to a definition a named domain owner maintains, and the agent returns that governed number with its source.
- Improvised and flagged: nothing in the map fits, so the agent calculates, labels the result as unofficial and logs the question for the likely owner.
An answer with neither mark, an improvised number that looks official, is exactly what this design exists to catch.
Neither a map nor a central semantic layer will ever be complete, and either one can sign some answers and flag the rest. The difference is what happens once a gap is found. In a central layer, it lands in the data team’s backlog, with a quarterly release cadence. In the mesh, it goes to the domain that owns the meaning, the domain defines it in its own app next week, and the map just gets a new entry on where to find it. The questions at the map’s edges tell the domain owners what to build next.
Your map will never cover every question. It only has to keep updating and be honest about where it ends.
COMING UP IN THIS SERIES
- Part 9: Will AI Eat BI? An AI assistant can build a sales director a beautiful dashboard in twenty minutes, but where will it live, and who will own it, a year from now? Why AI-built dashboards will replace many reports and spreadsheets, but not a governed analytics platform.